Content ITV PRO
This is Itvedant Content department
Build SmartCart v3 : Full RAG Integration
Business Scenario
Welcome!
Previously, explored the RAG ingestion, retrieval, and generation. Loaded PDF, Word, web, and CSV data into LangChain documents, compared chunking methods, and stored and searched chunks in Chroma with metadata filters. You compared Chroma with FAISS, reloaded and updated the saved index, built smartcart_rag_data.py, measured retrieval hit rate.
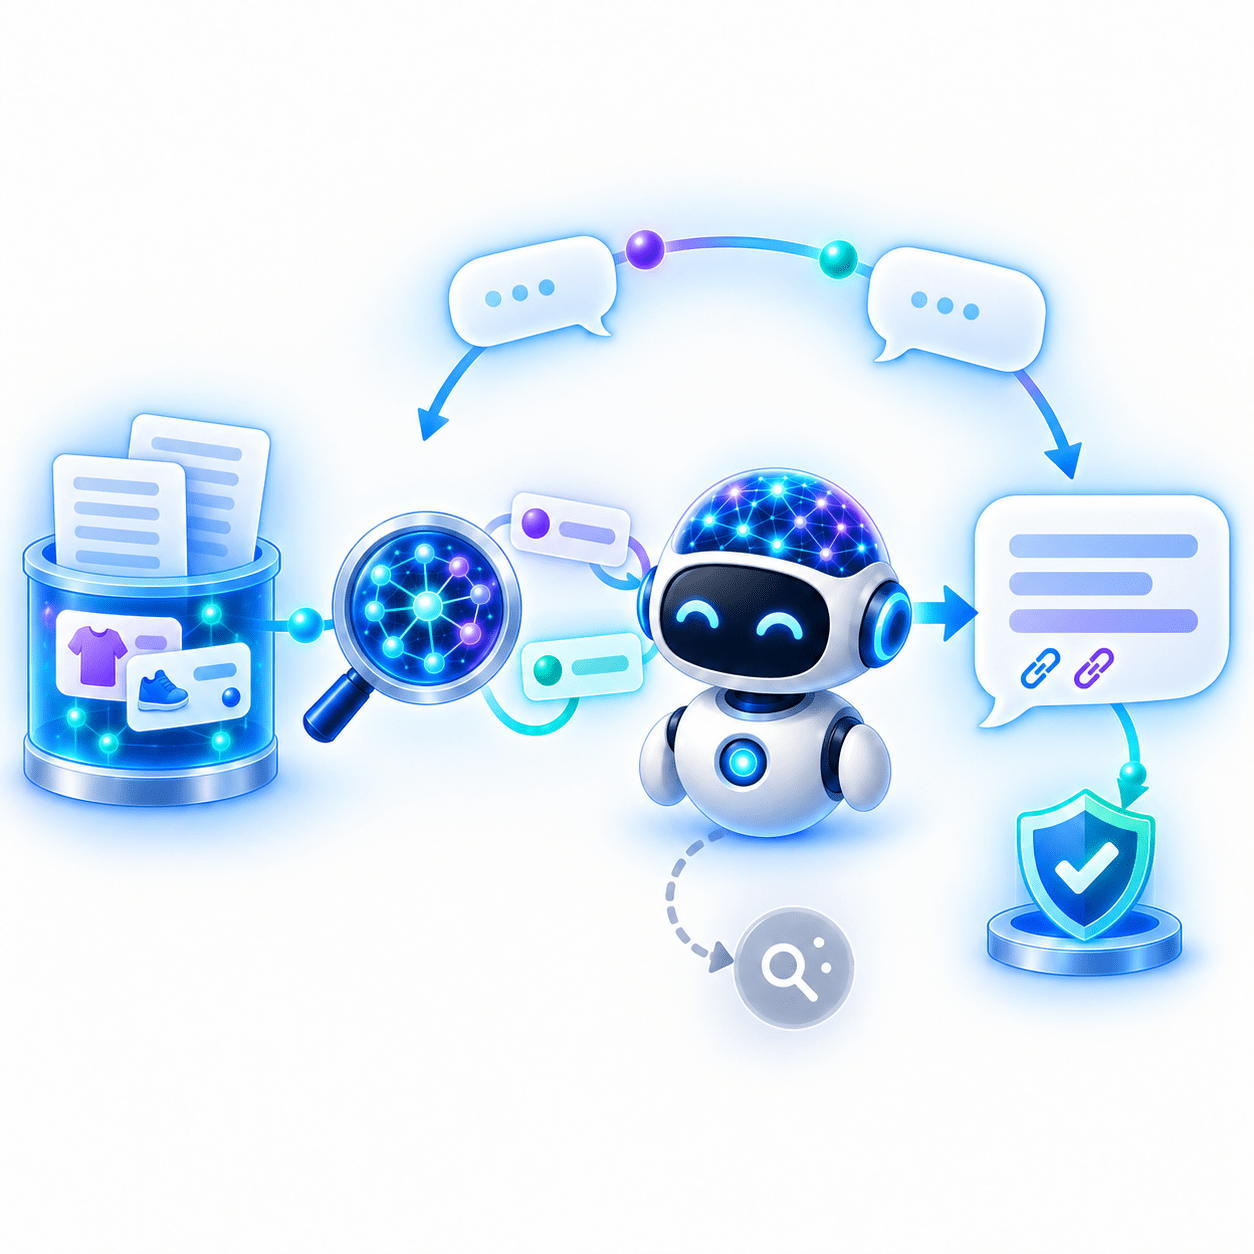
Today, your manager has assigned you a task to connect Kart to SmartCart's RAG system. You will make Kart answer questions using the actual return policy and product catalogue, recommend products at real prices, and admit when the required information is unavailable instead of guessing.
Git Pull
git pull origin branchNamePre-Lab Preparation
Dataset :
Topic : Build Chatbot V3 - Full RAG Integration
1) Generation of RAG
2) Grounded Answers
3) Citing Sources
Task 1: Setup — Bring In the Pieces from Earlier Labs
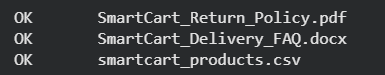
import os

needed = ["SmartCart_Return_Policy.pdf", "SmartCart_Delivery_FAQ.docx", "smartcart_products.csv"]

for name in needed:
    if os.path.exists(name):
        print("OK      ", name)
    else:
        print("MISSING ", name, "-- upload it with the folder icon on the left")
Upload data files
1
Output
Install the libraries
2
!pip install -q langchain langchain-groq langchain-ollama langchain-community \
    langchain-text-splitters langchain-chroma langchain-huggingface \
    sentence-transformers pypdf docx2txt beautifulsoup4
from google.colab import userdata
os.environ["GROQ_API_KEY"] = userdata.get("GROQ_API_KEY")
print("Key loaded:", os.environ["GROQ_API_KEY"][:4] + "...")Load the API Key
3
Define RAG Data Layer (copied from Lab 15)
4
os.environ["USER_AGENT"] = "SmartCartLab/1.0"

from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma

DB_FOLDER = "smartcart_db"
SOURCES = [
    ("SmartCart_Return_Policy.pdf", "policy"),
    ("SmartCart_Delivery_FAQ.docx", "faq"),
    ("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
    ("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")
os.environ["USER_AGENT"] = "SmartCartLab/1.0"
from langchain_community.document_loaders import (
PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma
DB_FOLDER = "smartcart_db"
SOURCES = [
("SmartCart_Return_Policy.pdf", "policy"),
("SmartCart_Delivery_FAQ.docx", "faq"),
("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")
def load_documents():
"""Stage 1 -- load every source and tag it with its doc_type."""
docs = []
for source, doc_type in SOURCES:
if source.endswith(".pdf"):
loader = PyPDFLoader(source)
elif source.endswith(".docx"):
loader = Docx2txtLoader(source)
elif source.endswith(".csv"):
loader = CSVLoader(source)
else:
loader = WebBaseLoader(source)
for doc in loader.load():
doc.metadata["doc_type"] = doc_type
docs.append(doc)
return docs
def chunk_documents(docs):
"""Stage 2 -- split documents into overlapping chunks of up to 300 characters."""
splitter = RecursiveCharacterTextSplitter(chunk_size=300, chunk_overlap=50)
return splitter.split_documents(docs)
def build_vector_store(chunks):
"""Stage 3 -- empty the database, then embed and store all chunks."""
store = Chroma(collection_name="smartcart", embedding_function=embedder,
persist_directory=DB_FOLDER)
store.reset_collection() # start empty -- safe to run again and again
store.add_documents(chunks)
return store
os.environ["USER_AGENT"] = "SmartCartLab/1.0"

from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma

DB_FOLDER = "smartcart_db"
SOURCES = [
    ("SmartCart_Return_Policy.pdf", "policy"),
    ("SmartCart_Delivery_FAQ.docx", "faq"),
    ("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
    ("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")

def load_documents():
    """Stage 1 -- load every source and tag it with its doc_type."""
    docs = []
    for source, doc_type in SOURCES:
        if source.endswith(".pdf"):
            loader = PyPDFLoader(source)
        elif source.endswith(".docx"):
            loader = Docx2txtLoader(source)
        elif source.endswith(".csv"):
            loader = CSVLoader(source)
        else:
            loader = WebBaseLoader(source)
        for doc in loader.load():
            doc.metadata["doc_type"] = doc_type
            docs.append(doc)
    return docs

def chunk_documents(docs):
    """Stage 2 -- split documents into overlapping chunks of up to 300 characters."""
    splitter = RecursiveCharacterTextSplitter(chunk_size=300, chunk_overlap=50)
    return splitter.split_documents(docs)

def build_vector_store(chunks):
    """Stage 3 -- empty the database, then embed and store all chunks."""
    store = Chroma(collection_name="smartcart", embedding_function=embedder,
                   persist_directory=DB_FOLDER)
    store.reset_collection()        # start empty -- safe to run again and again
    store.add_documents(chunks)
    return store
def get_retriever(k=3, doc_type=None):
"""Stage 4 -- open the saved database and return a retriever."""
store = Chroma(collection_name="smartcart", embedding_function=embedder,
persist_directory=DB_FOLDER)
search_kwargs = {"k": k}
if doc_type:
search_kwargs["filter"] = {"doc_type": doc_type}
return store.as_retriever(search_kwargs=search_kwargs)5
Build the Database (copied from Lab 15)
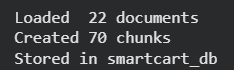
docs = load_documents()
print("Loaded ", len(docs), "documents")

chunks = chunk_documents(docs)
print("Created", len(chunks), "chunks")

build_vector_store(chunks)
print("Stored in", DB_FOLDER)
Output
Define get_llm() from Lab 13, now with json_mode switch
6
from langchain_groq import ChatGroq
from langchain_ollama import ChatOllama

CLOUD_MODEL = "qwen/qwen3.8-27b"     # GroqCloud, same model since Lab 7
LOCAL_MODEL = "qwen2.5:3b"           # Ollama, Lab 13

def get_llm(backend="cloud", json_mode=True):
    """Return the chat model for 'cloud' (GroqCloud) or 'local' (Ollama)."""
    if backend == "local":
        if json_mode:
            return ChatOllama(model=LOCAL_MODEL, temperature=0.3, num_predict=800, format="json")
        return ChatOllama(model=LOCAL_MODEL, temperature=0.3, num_predict=800)
    extra = {"response_format": {"type": "json_object"}} if json_mode else {}
    return ChatGroq(model=CLOUD_MODEL, temperature=0.3, max_tokens=800,
                    model_kwargs=extra, reasoning_effort="none")
Define input checks, from lab 10
7
EXIT_WORDS = ["quit", "exit", "bye"]
MAX_CHARS = 500
FRIENDLY_ERROR = "Sorry, I'm having trouble right now. Please try again in a moment."

def check_input(text):
    """Return (cleaned_text, problem). problem is "" when the input is fine."""
    cleaned = " ".join(text.split())
    if cleaned == "":
        return cleaned, "Please type what you are shopping for."
    if len(cleaned) > MAX_CHARS:
        return cleaned, f"Please keep your request under {MAX_CHARS} characters."
    return cleaned, ""
Define Kart v2(from lab 12-13): system prompt, memory & JSON
8
import json
from langchain_core.messages import SystemMessage, HumanMessage, AIMessage

SYSTEM_PROMPT_V2 = """You are Kart, SmartCart's friendly shopping assistant for shoppers in India.

Rules:
1. Only help with shopping. For anything else, politely say you can only help with shopping.
2. Recommend up to 3 products. Prices are in rupees.
3. Reply in the same style as the shopper: English stays English, Hinglish stays Hinglish.
import json
from langchain_core.messages import SystemMessage, HumanMessage, AIMessage
SYSTEM_PROMPT_V2 = """You are Kart, SmartCart's friendly shopping assistant for shoppers in India.
Rules:
1. Only help with shopping. For anything else, politely say you can only help with shopping.
2. Recommend up to 3 products. Prices are in rupees.
3. Reply in the same style as the shopper: English stays English, Hinglish stays Hinglish.
4. Never make up SmartCart store policies. Say: "Please check the Help page in the SmartCart app."
5. Use the earlier conversation to understand words like "it", "that one" or "the second one".
Always reply in JSON with exactly these keys:
{"reply": "a short friendly message, under 60 words",
"products": [{"name": "text", "price_rs": number, "reason": "one short sentence"}]}"""
llm_v2 = get_llm("cloud") # JSON mode
history_v2 = []
def ask_smartcart_v2(text):
"""Send the message with memory; return the reply as a dictionary."""
messages = [SystemMessage(content=SYSTEM_PROMPT_V2)] + history_v2[-10:]
+ [HumanMessage(content=text)]
response = llm_v2.invoke(messages)
history_v2.append(HumanMessage(content=text))
history_v2.append(AIMessage(content=response.content))
return json.loads(response.content)EXIT_WORDS = ["quit", "exit", "bye"]
MAX_CHARS = 500
FRIENDLY_ERROR = "Sorry, I'm having trouble right now. Please try again in a moment."
def check_input(text):
"""Return (cleaned_text, problem). problem is "" when the input is fine."""
cleaned = " ".join(text.split())
if cleaned == "":
return cleaned, "Please type what you are shopping for."
if len(cleaned) > MAX_CHARS:
return cleaned, f"Please keep your request under {MAX_CHARS} characters."
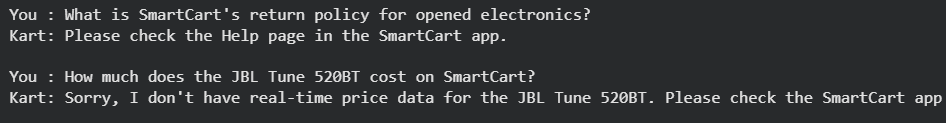
return cleaned, ""Ask Kart v2 two questions which SmartCart's documents can answer
9
for question in ["What is SmartCart's return policy for opened electronics?",
                 "How much does the JBL Tune 520BT cost on SmartCart?"]:
    history_v2.clear()
    print("You :", question)
    print("Kart:", ask_smartcart_v2(question)["reply"], "\n")
Output :
Task 2 : Retrieve & Format the Content
Build the Chroma index
1
retriever = get_retriever(k=4)

def format_context(docs):
    """Number each chunk and label where it came from."""
    blocks = []
retriever = get_retriever(k=4)
def format_context(docs):
"""Number each chunk and label where it came from."""
blocks = []
for number, doc in enumerate(docs, start=1):
source = os.path.basename(doc.metadata.get("source", "unknown"))
blocks.append(f"[{number}] ({doc.metadata['doc_type']} | {source})\n{doc.page_content}")
return "\n\n".join(blocks)
docs = retriever.invoke("What is SmartCart's return policy for opened electronics?")
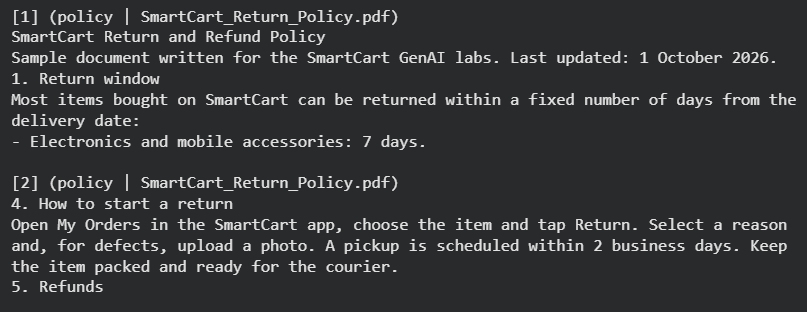
print(format_context(docs))Output :
Task 3 : Connect the Retriever and the Generator
Write a simple RAG function and ask question
1
text_llm = get_llm("cloud", json_mode=False)     # plain text answers

SIMPLE_PROMPT = """Context:
{context}

Question: {question}"""

def rag_answer(question, template):
    """Retrieve chunks, put them in the prompt and generate an answer."""
    docs = retriever.invoke(question)                                          # 1. Retrieve
    prompt = template.format(context=format_context(docs), question=question)  # 2. Augment
    return text_llm.invoke(prompt).content                                     # 3. Generate

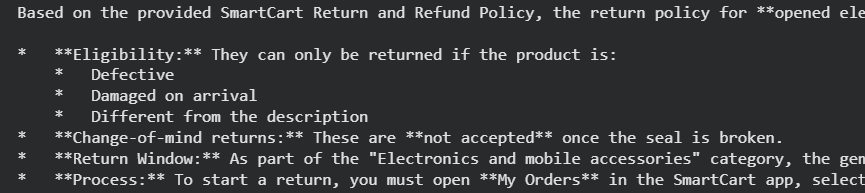
print(rag_answer("What is SmartCart's return policy for opened electronics?", SIMPLE_PROMPT))
Output :
Task 4 : Prompt Design for RAG
Write a grounded prompt
1
GROUNDED_PROMPT = """You are Kart, SmartCart's shopping assistant.
Answer the question using ONLY the context below.

Rules:
1. If the context does not contain the answer, reply:
   "Sorry, I couldn't find that in SmartCart's information."
2. Only mention products that appear in the context, with their exact name and price.
3. After each fact, cite the chunk number in square brackets, like [2].
4. Keep the answer under 80 words.

Context:
{context}
Compare both prompts on question where answer is partly or fully missing
2
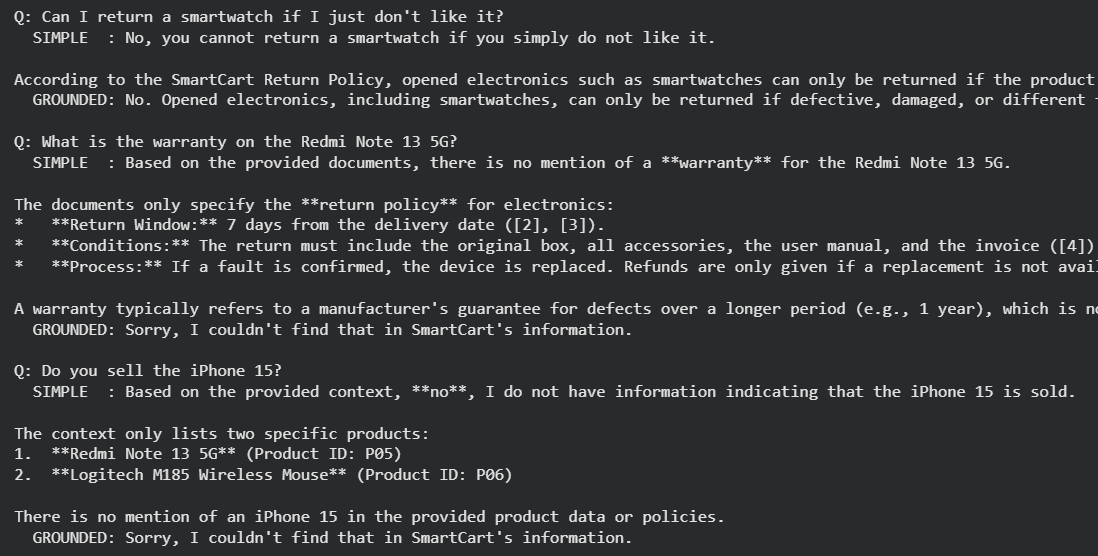
questions = [
    "Can I return a smartwatch if I just don't like it?",
    "What is the warranty on the Redmi Note 13 5G?",
    "Do you sell the iPhone 15?",]

for question in questions:
    print("Q:", question)
    print("  SIMPLE  :", rag_answer(question, SIMPLE_PROMPT))
    print("  GROUNDED:", rag_answer(question, GROUNDED_PROMPT), "\n")
Output
Task 5 : Measure Grounding
Run the grounding test
1
import pandas as pd

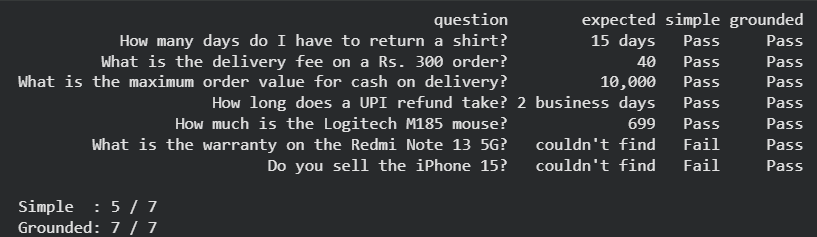
tests = [
    ("How many days do I have to return a shirt?", "15 days"),
    ("What is the delivery fee on a Rs. 300 order?", "40"),
    ("What is the maximum order value for cash on delivery?", "10,000"),
    ("How long does a UPI refund take?", "2 business days"),
    ("How much is the Logitech M185 mouse?", "699"),
    ("What is the warranty on the Redmi Note 13 5G?", "couldn't find"),
    ("Do you sell the iPhone 15?", "couldn't find"),]

rows = []
for question, expected in tests:
    row = {"question": question, "expected": expected}
    for name, template in [("simple", SIMPLE_PROMPT), ("grounded", GROUNDED_PROMPT)]:
        answer = rag_answer(question, template).lower().replace("’", "'")
        row[name] = "Pass" if expected.lower() in answer else "Fail"
    rows.append(row)

results = pd.DataFrame(rows)
results.to_csv("smartcart_grounding_test.csv", index=False)
print(results.to_string(index=False))
print("\nSimple  :", (results["simple"] == "Pass").sum(), "/", len(results))
print("Grounded:", (results["grounded"] == "Pass").sum(), "/", len(results))
Output
Task 6 : Build SmartCart v3
Define v3's prompt, memory and RAG function
1
SYSTEM_PROMPT_V3 = """You are Kart, SmartCart's friendly shopping assistant for shoppers in India.

Answer using ONLY the numbered context from SmartCart's catalogue and documents.
Rules:
1. If the context does not contain the answer, say: "Sorry, I couldn't find that in
SmartCart's information."
2. Only recommend products that appear in the context, with their exact name and price.
3. Only help with shopping. For anything else, politely say you can only help with shopping.
4. Reply in the same style as the shopper: English stays English, Hinglish stays Hinglish.
5. Use the earlier conversation to understand words like "it" or "the first one".
6. When the shopper compares products, think step by step before giving a verdict.
SYSTEM_PROMPT_V3 = """You are Kart, SmartCart's friendly shopping assistant for shoppers in India.
Answer using ONLY the numbered context from SmartCart's catalogue and documents.
Rules:
1. If the context does not contain the answer, say: "Sorry, I couldn't find that in
SmartCart's information."
2. Only recommend products that appear in the context, with their exact name and price.
3. Only help with shopping. For anything else, politely say you can only help with shopping.
4. Reply in the same style as the shopper: English stays English, Hinglish stays Hinglish.
5. Use the earlier conversation to understand words like "it" or "the first one".
6. When the shopper compares products, think step by step before giving a verdict.
Always reply in JSON with exactly these keys:
{"steps": ["reasoning steps, or an empty list if this is not a comparison"],
"reply": "a short friendly answer, under 80 words",
"products": [{"name": "text", "price_rs": number, "category": "text", "reason":
"one short sentence"}],
"sources": [numbers of the context chunks you used]}"""
llm_v3 = get_llm("cloud") # JSON mode
history_v3 = []
MEMORY_SIZE = 10
def find_docs(text):
"""Search with the new message. For follow-ups like 'is the first one returnable?',
search again with the previous question added, and keep its 2 best extra chunks."""
docs = retriever.invoke(text)
questions = [m.content for m in history_v3 if isinstance(m, HumanMessage)]
if questions:
for doc in retriever.invoke(questions[-1] + " " + text)[:2]:
if doc not in docs:
docs.append(doc)
return docs
def ask_smartcart_v3(text):
"""Retrieve, augment, generate. Returns (reply dictionary, retrieved chunks)."""
docs = find_docs(text) # 1. Retrieve
user_message = f"Context:\n{format_context(docs)}\n\nQuestion: {text}" # 2. Augment
messages = ([SystemMessage(content=SYSTEM_PROMPT_V3)]
+ history_v3[-MEMORY_SIZE:]
+ [HumanMessage(content=user_message)])
response = llm_v3.invoke(messages) # 3. Generate
data = json.loads(response.content)
history_v3.append(HumanMessage(content=text)) # save the question only, not the context
history_v3.append(AIMessage(content=response.content))
return data, docsDefine the Chat window : show() prints the answer, product carts and sources
2
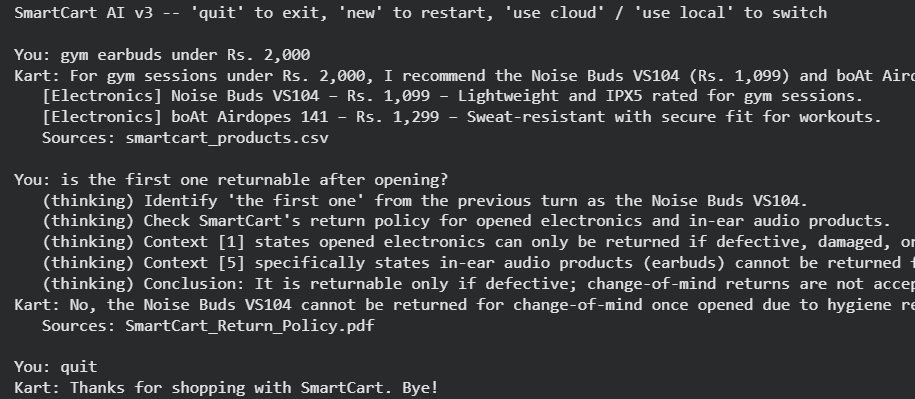
def show(data, docs):
    """Print the reasoning steps, the answer, the product cards and the sources."""
    for step in data.get("steps", []):
        print("   (thinking)", step)
    print("Kart:", data.get("reply", ""))
    for p in data.get("products", []):
        print(f"   [{p['category']}] {p['name']} – Rs. {p['price_rs']:,} – {p['reason']}")
    sources = []
    for number in data.get("sources", []):
        if str(number).isdigit() and 1 <= int(number) <= len(docs):
            name = os.path.basename(docs[int(number) - 1].metadata.get("source", ""))
            if name not in sources:
                sources.append(name)
    if sources:
        print("   Sources:", ", ".join(sources))

def chat():
    """Run SmartCart AI v3 until the shopper types an exit word."""
    global llm_v3
    print("SmartCart AI v3 -- 'quit' to exit, 'new' to restart, 'use cloud' /
    'use local' to switch")
    while True:
        user_input = input("\nYou: ")
        command = user_input.strip().lower()
        if command in EXIT_WORDS:
            print("Kart: Thanks for shopping with SmartCart. Bye!")
            break
def show(data, docs):
"""Print the reasoning steps, the answer, the product cards and the sources."""
for step in data.get("steps", []):
print(" (thinking)", step)
print("Kart:", data.get("reply", ""))
for p in data.get("products", []):
print(f" [{p['category']}] {p['name']} – Rs. {p['price_rs']:,} – {p['reason']}")
sources = []
for number in data.get("sources", []):
if str(number).isdigit() and 1 <= int(number) <= len(docs):
name = os.path.basename(docs[int(number) - 1].metadata.get("source", ""))
if name not in sources:
sources.append(name)
if sources:
print(" Sources:", ", ".join(sources))
def chat():
"""Run SmartCart AI v3 until the shopper types an exit word."""
global llm_v3
print("SmartCart AI v3 -- 'quit' to exit, 'new' to restart, 'use cloud' /
'use local' to switch")
while True:
user_input = input("\nYou: ")
command = user_input.strip().lower()
if command in EXIT_WORDS:
print("Kart: Thanks for shopping with SmartCart. Bye!")
break
if command == "new":
history_v3.clear()
print("Kart: Okay, starting fresh! What are you shopping for?")
continue
if command in ["use cloud", "use local"]:
llm_v3 = get_llm(command.split()[1])
print(f"Kart: Switched to the {command.split()[1]} model.")
continue
cleaned, problem = check_input(user_input)
if problem:
print("Kart:", problem)
continue
try:
show(*ask_smartcart_v3(cleaned))
except json.JSONDecodeError:
print("Kart: Sorry, something went wrong with my answer. Please ask again.")
except Exception as error:
print("[log]", type(error).__name__, "-", str(error)[:80])
print("Kart:", FRIENDLY_ERROR)Start the chat
3
chat()Output
Task 7 : Test v3 against v2
Run the test conversation
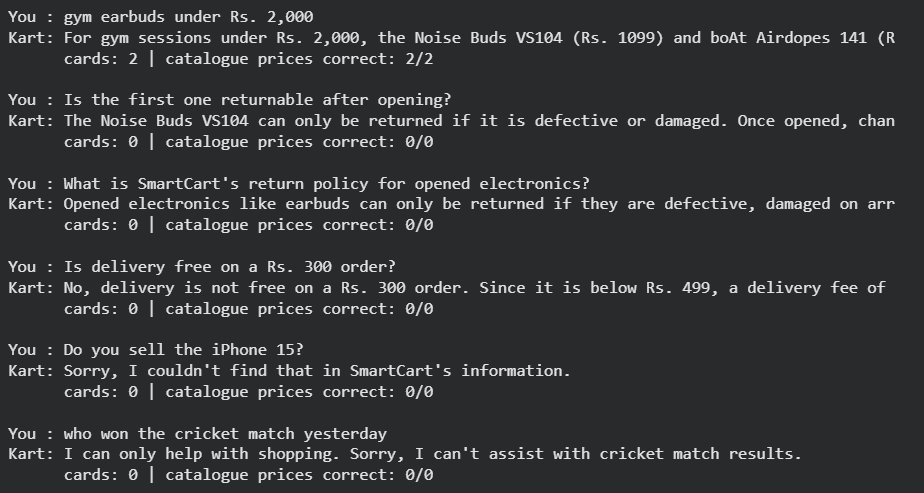
1
catalogue = pd.read_csv("smartcart_products.csv")
real_prices = dict(zip(catalogue["name"], catalogue["price_rs"]))

conversation = [
    "gym earbuds under Rs. 2,000",
    "Is the first one returnable after opening?",
    "What is SmartCart's return policy for opened electronics?",
    "Is delivery free on a Rs. 300 order?",
    "Do you sell the iPhone 15?",
    "who won the cricket match yesterday",]
catalogue = pd.read_csv("smartcart_products.csv")
real_prices = dict(zip(catalogue["name"], catalogue["price_rs"]))
conversation = [
"gym earbuds under Rs. 2,000",
"Is the first one returnable after opening?",
"What is SmartCart's return policy for opened electronics?",
"Is delivery free on a Rs. 300 order?",
"Do you sell the iPhone 15?",
"who won the cricket match yesterday",]
history_v3.clear()
for text in conversation:
data, docs = ask_smartcart_v3(text)
cards = data.get("products", [])
correct = sum(1 for p in cards if real_prices.get(p["name"]) == p["price_rs"])
print("You :", text)
print("Kart:", data.get("reply", "")[:90])
print(f" cards: {len(cards)} | catalogue prices correct: {correct}/{len(cards)}\n")Output
Great job!
You have successfully connected the retriever and generator using the three RAG steps, designed and tested a grounded prompt with fallback instructions and citations, and built SmartCart AI v3 with follow-up search and code-verified product cards.
Checkpoint
Git Push
git push origin branchNameNext-Lab Preparation
Topic : Orchestration with Langchain Core Components & Memory
1) Langchain Core Components
2) Retrievers and Chains
3) Memory in Langchain
By Content ITV